When it comes to monitoring, I’m a huge Grafana fan.
Tons of features, rock-solid, free to self-host... all green lights for me!
VDC already comes with its own reporting and dashboards, but hey, you know me, I want to build my own playground, exactly the way I like it. Home sweet home! 😎
So the big question is: how do I get VDC metrics out of VDC and into my own monitoring stack?
The answer: VDC SIEM integration!
Summary:
- What is VDC SIEM integration?
- Catching VDC events with Telegraf HTTP Listener
- Wiring it up with the generic webhook integration
- Bringing it all to life in Grafana
1/ What is VDC SIEM integration?
In a nutshell, Veeam Data Cloud Integrations is basically the event-export door of VDC.
It allows VDC to push security, audit, and operational events outside the platform, so you can mix them with the rest of your monitoring world, feed a SIEM, build your own dashboards, or trigger some automation magic.
Today, VDC supports:
- Splunk through HTTP Event Collector
- CrowdStrike LogScale / Next-Gen SIEM
- Generic Webhook for pretty much any HTTP endpoint, with support for custom authentication and HTTP headers
And this last one is exactly where the fun starts for us. 😁
So basically: VDC generates the events, the integration pushes them out, and from there... your playground, your rules!
Here are two useful documentation links covering this feature in more detail:
- User Guide: Veeam Data Cloud Integrations - Veeam Data Cloud User Guide
- Event Reference: About Veeam Data Cloud Event Reference - Veeam Data Cloud Event Reference
2/ Catching VDC events with Telegraf HTTP Listener
So now comes the obvious question: where do we actually receive all those VDC events? This is where Telegraf joins the party!
Telegraf is a lightweight, open-source telemetry agent that does one job really well: moving data from A to B without making a fuss.
It can collect metrics and events from tons of different sources, optionally transform them along the way, then forward everything to platforms like InfluxDB.
Its big superpower is the plugin ecosystem. With 400+ plugins, Telegraf can talk to JSON endpoints, Prometheus, databases, cloud services, containers, IoT devices, message queues, and plenty more.
So, in one sentence: Telegraf is the collection and transport layer sitting between your data sources and your monitoring platform, quietly keeping the data flowing in the background.
Using the correct input
We’re going to use a dedicated Telegraf input called [[inputs.http_listener_v2]].
Telegraf HTTP Listener v2 basically turns Telegraf into a small HTTP inbox for your metrics.
Instead of Telegraf going out hunting for data, it simply sits there and waits for external applications to push information to it. Incoming HTTP requests are accepted, converted into Telegraf metrics, then forwarded to whatever output you already use, such as InfluxDB.
Simple setup, nice little data pipeline, and exactly what we need to catch VDC events on their way to Grafana.
Here’s the official documentation to keep exploring: https://docs.influxdata.com/telegraf/v1/input-plugins/http_listener_v2/
The http listener v2 configuration for VDC events
To configure Telegraf inputs and outputs, edit /etc/telegraf/telegraf.conf.
This file uses TOML syntax, and each Telegraf plugin is declared inside double brackets. For our case, the plugin we want is: [[inputs.http_listener_v2]]
➡️ First, locate that section in the configuration file and uncomment it.
Then configure the HTTP path where telegraf will listen for the JSON events pushed by VDC.
[[inputs.http_listener_v2]]
  service_address = ":8186"
  paths   = ["/vdc/events"]
  methods = ["POST"]

  basic_username = "youruser"
  basic_password = "yourpassword"

  data_format = "json_v2"
With this first part in place, Telegraf starts a small HTTP listener on port 8186 and waits for incoming VDC events on the /vdc/events path.
As you can see, the listener is protected by an authentication gate, so random visitors cannot just stroll in.
So your endpoint becomes:http://IP:8186/vdc/events
That is now the little landing zone where VDC will drop its JSON events.
➡️ Next, we need to explain to telegraf how to organize each event received from VDC: where to store it, and at what time.
- For the timestamp, Telegraf does not simply use the moment the message arrives. Instead, it reads the actual time when the event happened in VDC. That matters because events can sometimes arrive late or even out of order.
The final line simply tells Telegraf how to read that timestamp, using the standard international format, for example2026-09-30T18:19:35Z. - For the storage, we simply store it under "vdc_events" name in the database.
  [[inputs.http_listener_v2.json_v2]]
    measurement_name = "vdc_events"
    timestamp_path   = "timestamp"
    timestamp_format = "2006-01-02T15:04:05Z07:00"
In short: every VDC event lands in the right place and at the right moment on the timeline.
➡️ Next part of the configuration tells telegraf what to extract from each VDC event, and how to organize it once received.
Each VDC event arrives as a fairly raw detailed JSON message. Telegraf does not need to keep everything in the same way, so we split the useful information into 2 families:
- Tags are the things we want to filter, group, and slice in Grafana. Think event type, source, user, workload, or operation status. These are the values that make questions like “show me failed backups” or “group activity by user” easy to answer.
- Fields are the detailed payload. They are useful to display, inspect, or calculate with, but not ideal for grouping: technical IDs, backup policy names, restore reasons, success counters, error counters, and similar details.
Every extracted value is also marked as optional.
VDC events do not all carry the same properties, so if one field is missing, telegraf simply moves on instead of throwing a little tantrum.
   # TAGS (bounded values, used for filters / GROUP BY)
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "type"
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "source"
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "actor.kind"
      rename = "actor_kind"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "actor.identifier"
      rename = "actor"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.workload.type"
      rename = "workload"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.audit.action"
      rename = "audit_action"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.audit.actionGroup"
      rename = "action_group"
      optional = true

    # raw status fields, merged into "result" by the processor below
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.status.status"
      rename = "st_backup"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.lifecycle.status"
      rename = "st_restore"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.login.status"
      rename = "st_login"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.roleChanged.action"
      rename = "st_role"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.statusChanged.action"
      rename = "st_user"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.changed.status"
      rename = "st_tenant"
      optional = true
    [[inputs.http_listener_v2.json_v2.tag]]
      path = "data.config.destinationKind"
      rename = "st_datakind"
      optional = true

    # FIELDS (free text / IDs)
    [[inputs.http_listener_v2.json_v2.field]]
      path = "specversion"
      type = "string"
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.tenant.id"
      rename = "tenant_id"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.changed.name"
      rename = "tenant_name"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.policy.id"
      rename = "policy_id"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.policy.policyName"
      rename = "policy_name"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.execution.id"
      rename = "execution_id"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.audit.targetDisplayName"
      rename = "target"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.roleChanged.roleName"
      rename = "role_name"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.user.primaryEmail"
      rename = "user_email"
      type = "string"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.search.searchValue"
      rename = "search_value"
      type = "string"
      optional = true

    # Restore session details
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.config.reason"
      rename = "restore_reason"
      type = "string"
      optional = true

    # Restore Item Statistics
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.itemStats.totalItems"
      rename = "items_total"
      type = "int"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.itemStats.itemsSuccessful"
      rename = "items_successful"
      type = "int"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.itemStats.itemsWarning"
      rename = "items_warning"
      type = "int"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.itemStats.itemsFailed"
      rename = "items_failed"
      type = "int"
      optional = true
    [[inputs.http_listener_v2.json_v2.field]]
      path = "data.itemStats.itemsSkipped"
      rename = "items_skipped"
      type = "int"
      optional = true
In short: Telegraf opens each VDC JSON package, keeps the useful bits, puts labels on what should be searchable, stores the detailed values separately, and leaves us with nice clean data ready for Grafana.
➡️ This last part is basically the translator of the whole setup, and I’ll be honest, it gets pretty hardcore! 😅
Huge thanks to my buddy Claude for helping me build this configuration, because this is definitely way beyond my current Telegraf wizardry. ❤️
VDC events arrive with very technical names such as vdc.org_v0.login_v0.
Perfectly fine for machines, slightly less exciting for humans staring at a Grafana dashboard.
So this small script runs inside telegraf for every incoming VDC event and turns all that technical language into something much easier to understand.
For each event, it adds four useful pieces of information:
- A friendly name:
vdc.org_v0.login_v0becomes something likeUser Login, while backup and export events get clear names such asBackup ResultorBackup Data Exported. - A category: events are grouped into logical families such as identity and access, backup, restore, or data operations.
- A severity level: from
Infoall the way up toCritical, depending on what actually happened. - A normalized result: success, failure, added, exported, and so on. Different VDC events store their status in different places, so the script brings everything under one common field.
The script also does a little housekeeping along the way.
Email addresses are converted to lowercase so the same user does not magically become two different people, and temporary fields are removed once they have done their job.
And if a brand-new event type suddenly appears?
No panic. It is still kept, classified as Other, and its original technical name remains available until we decide how to translate it properly.
[[processors.starlark]]
  namepass = ["vdc_events"]
  source = '''
DATA_KIND = {"RESTORE": "Backup Data Restored", "COPY": "Backup Data Copied",
             "DOWNLOAD": "Backup Data Downloaded", "EXPORT": "Backup Data Exported"}
POLICY_SEV = {"Backup Policy Deleted": "Low", "Backup Policy Disabled": "Low",
              "Backup Policy Stopped": "High"}

def apply(metric):
    t = metric.tags.get("type", "")
    g = lambda k: metric.tags.get(k, "")
    event, cat, sev, res = t, "Other", "Info", ""

    if t == "vdc.org_v0.login_v0":
        event, cat, res = "User Login", "Access & Identity", g("st_login")
    elif t == "vdc.org_v0.user_v0.roleChanged_v0":
        event, cat, res = "Role " + g("st_role").title(), "Access & Identity", g("st_role")
    elif t == "vdc.org_v0.user_v0.statusChanged_v0":
        event, cat, res = "User Status Changed", "Access & Identity", g("st_user")
    elif t == "vdc.org_v0.tenant_v0.accessed_v0":
        event, cat = "Workload Tenant Accessed", "Access & Identity"
    elif t == "vdc.org_v0.tenant_v0.changed_v0":
        event, cat, res = "Tenant Status Updated", "Tenant Management", g("st_tenant")
        if res == "DELETED":
            sev = "High"
    elif t == "vdc.workload_v0.tenant_v0.backup.policy_v0.execution_v0.status_v0":
        event, cat, res = "Backup Result", "Backup Execution", g("st_backup")
        sev = {"WARNING": "Medium", "FAILED": "High"}.get(res, "Info")
    elif t == "vdc.workload_v0.tenant_v0.restore.execution_v0.lifecycle_v0":
        res, cat = g("st_restore"), "Restore Execution"
        if res == "STARTED":
            event = "Restore Started"
        elif res == "ABORTED":
            event, sev = "Restore Stopped", "Medium"
        else:
            event = "Restore Result"
            sev = {"WARNING": "Low", "FAILED": "Critical"}.get(res, "Info")
    elif t == "vdc.workload_v0.tenant_v0.restore.execution_v0.config_v0":
        res, cat = g("st_datakind"), "Backup Data Operations"
        event = DATA_KIND.get(res, "Backup Data " + res)
    elif t == "vdc.workload_v0.tenant_v0.backup.policy_v0.execution_v0.objTypeStats_v0":
        event, cat = "Backup Object Type Statistics", "Backup Execution"
    elif t == "vdc.workload_v0.tenant_v0.restore.execution_v0.itemStats_v0":
        event, cat = "Restore Item Statistics", "Restore Execution"
    elif ".audit_v0." in t:
        event = g("audit_action") or t
        if ".backup.execution_v0" in t:
            cat = "Backup Execution"
        elif ".backup.policy_v0" in t:
            cat = "Backup Policy Operations"
        else:
            cat = "Backup Data Operations"
        sev = POLICY_SEV.get(event, "Info")

    actor = g("actor")
    if actor:
        metric.tags["actor"] = actor.lower()

    metric.tags["event"] = event
    metric.tags["category"] = cat
    metric.tags["severity"] = sev
    if res:
        metric.tags["result"] = res
    for k in ["st_backup", "st_restore", "st_login", "st_role", "st_user", "st_tenant", "st_datakind"]:
        metric.tags.pop(k, None)
    return metric
'''
In short: this script takes raw VDC event gibberish, cleans it up, classifies it, adds severity and context, and turns it into dashboard-friendly data that humans can actually enjoy reading.
Basically, this is where the raw telemetry gets a haircut, puts on a clean shirt, and gets ready for Grafana! Lol! 😆
➡️ And finally, the last part. (I promise, this time it really is the last one!😀): The output.
I’m still running an old InfluxDB1.8 setup with a pretty minimal telegraf configuration. I have to admit, it is not exactly the most modern or secure setup anymore, and sooner or later this project will probably be the excuse I need to finally upgrade it. 😉
But for now, this is what my lab is running, so this is what I’ll use here.
Feel free to adapt the configuration to whatever backend InfluxDB you are using.
We now need to tell Telegraf where to send all those nicely prepared VDC events.
In my case, that destination is InfluxDB, using the Telegraf output plugin: [[outputs.influxdb]]
[[outputs.influxdb]]
  urls = ["http://yourIP:8086"]
  database = "DB_name"

  username = "yourusername"
  password = "yourpassword"
And with that, our VDC events finally have somewhere to live before Grafana comes knocking.
For convenience, you’ll find below the complete [[inputs.http_listener_v2]] configuration:
3/ Wiring it up with the generic webhook integration
As mentioned above, VDC comes with 3 integration connectors: Splunk, CrowdStrike, and a Generic Webhook connector.
That last one is exactly what we need here.
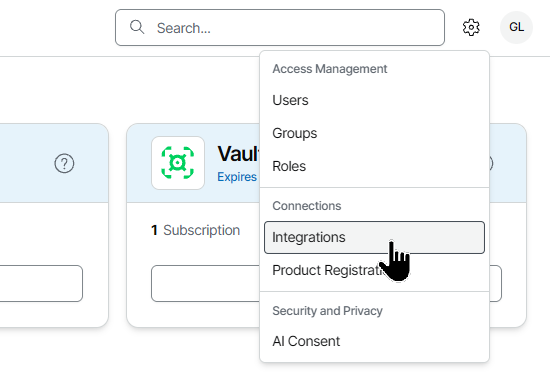
To access the integrations, login to your VDC organization, then click the gearbox icon in the top-right corner and open the Integrations section:
Then click the green Add integration button.
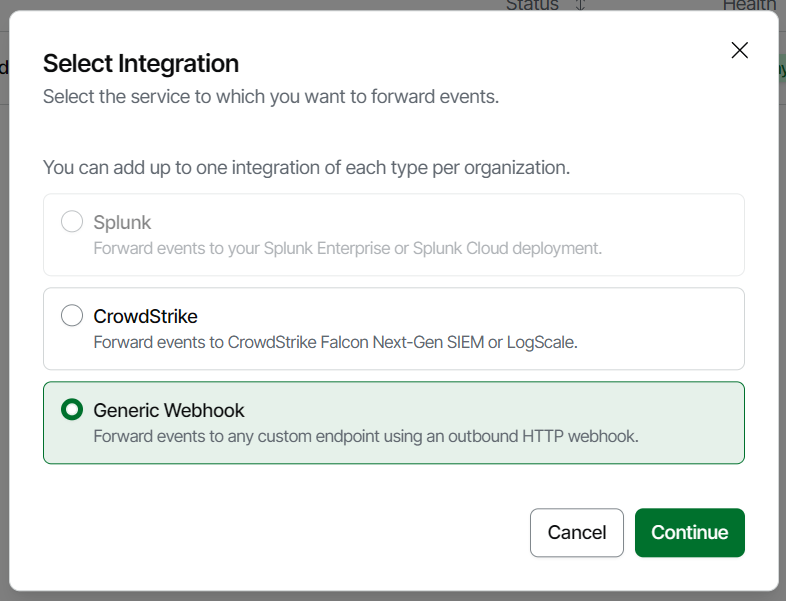
A small modal window will appear asking which type of integration you want to add to your organization.
Select "Generic Webhook":
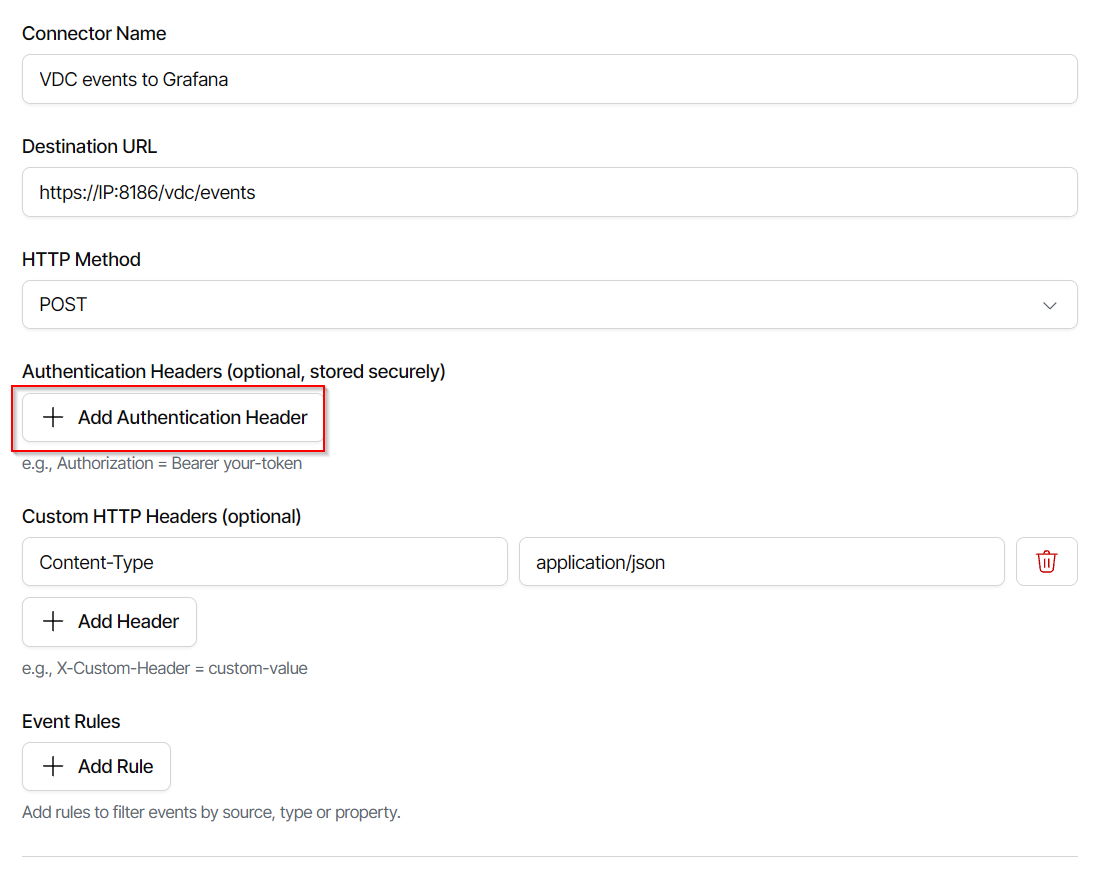
Fill up the needed information:
- Connector Name: Whatever name you want
- Destination URL: HTTPS address of your telegraf listner
That topic probably deserves its own article, but if you’re looking for a reverse proxy, I strongly recommend giving Zoraxy a try. It actually made me give up on Nginx Proxy Manager! 😉
Next, we need to define the authentication header. Remember, our webhook is protected, so we don’t want random untrusted visitors sending data to it.
Click Add Authentication Header, then add the same header expected by your telegraf listener:
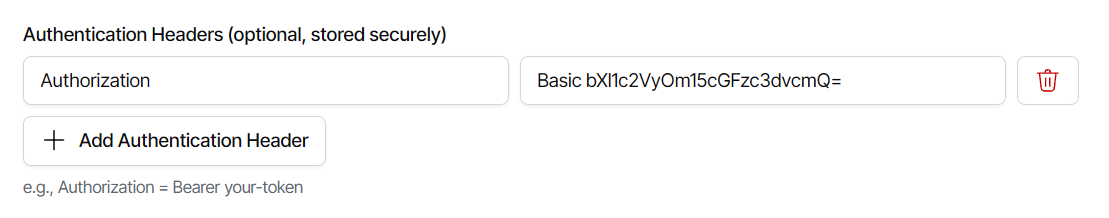
Now we need to encode the username and password from our telegraf HTTP listener configuration into Base64 for the Basic Authentication header.
Nothing too scary here, a simple Shell command will do the job:
echo -n 'myuser:mypassword' | base64then add your auth heard as the folllwing:
Keep everything else the same.
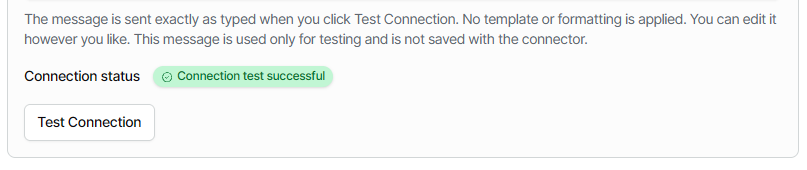
You can also test the connection using the "Test connection payload" field in the VDC configuration modal:
{
  "specversion": "20250815",
  "source": "CONTROLPLANE",
  "timestamp": "2026-09-30T10:00:00Z",
  "type": "vdc.org_v0.login_v0",
  "actor": { "identifier": "greg@greg.fr", "kind": "user" },
  "data": { "login": { "status": "SUCCESS" } }
}
This should confirm that the connection is working successfully:
Once done, save your VDC integration configuration.
Everything should now be working correctly on the VDC side.
4/ Bringing it all to life in Grafana
For this article, I’ll assume you already have Grafana running with InfluxDB connected as a data source. Otherwise, we might need another coffee and another article first! 😆☕
Grafana can use InfluxQL, the query language provided by InfluxDB, to query and aggregate the data stored in the database.
The results can then be displayed using the Grafana panel that best fits what you want to show. Tables, line charts, bar charts, pie charts, stats, and plenty more. Grafana gives you a lot of freedom to turn raw data into something actually useful to look at.
To build our VDC monitoring dashboard, we’ll simply create different panel types and query the data using InfluxQL.
As a first example, let’s display the total number of VDC events received by our webhook.
For that, I created a "Stat" panel and selected the InfluxDB data source where my VDC events are stored.
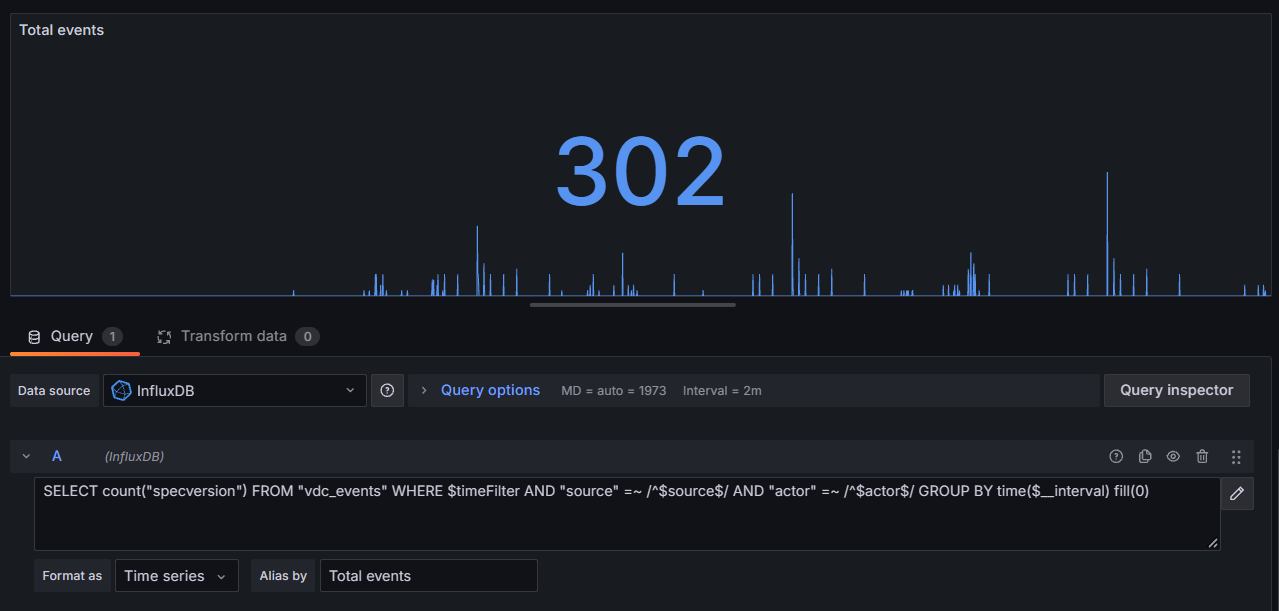
But before building our panels, we need to create 2 Grafana variables that will make the dashboard much more useful: "Source" and "Actor".
These variables will let us filter the entire dashboard later.
For example, "Source" can be used to focus on a specific VDC area such as Control Plane or Microsoft 365, while "Actor" lets us filter events generated by a specific connected user, such as userA, userB, or userC.
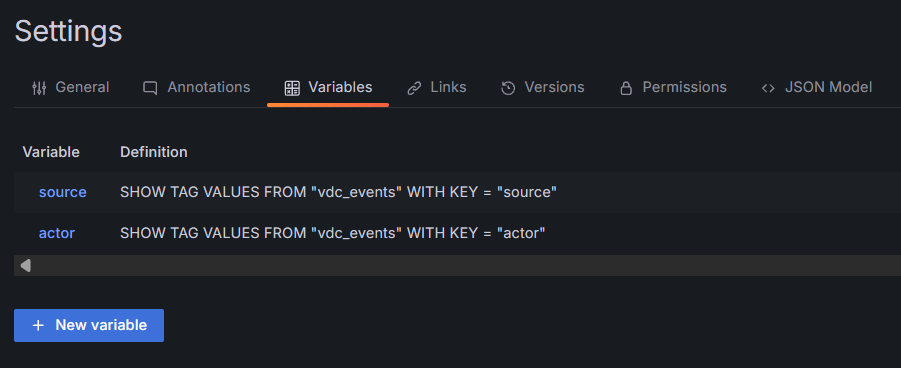
To create these variables, open your dashboard settings and go to the Variables tab.
- first called "Source" with the following query:
SHOW TAG VALUES FROM "vdc_events" WITH KEY = "source"
sort it by Alphabetical (asc) order.
select "Multi-value" and "include all options"
and in the field "Custom all value" type: ".*". - second called "Actor" with the following query:
SHOW TAG VALUES FROM "vdc_events" WITH KEY = "actor"
sort it by Alphabetical (asc) order.
select "Multi-value" and "include all options"
and in the field "Custom all value" type: ".*".
Once everything is configured, you should see your two shiny new variables appear at the top of the dashboard, just like below:
Now you can start creating your different Grafana panels and make all those VDC events speak the way you want.
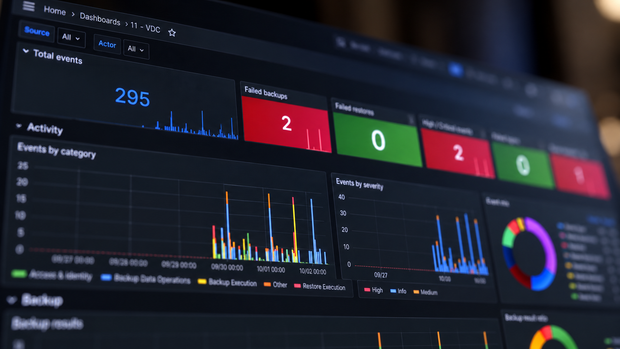
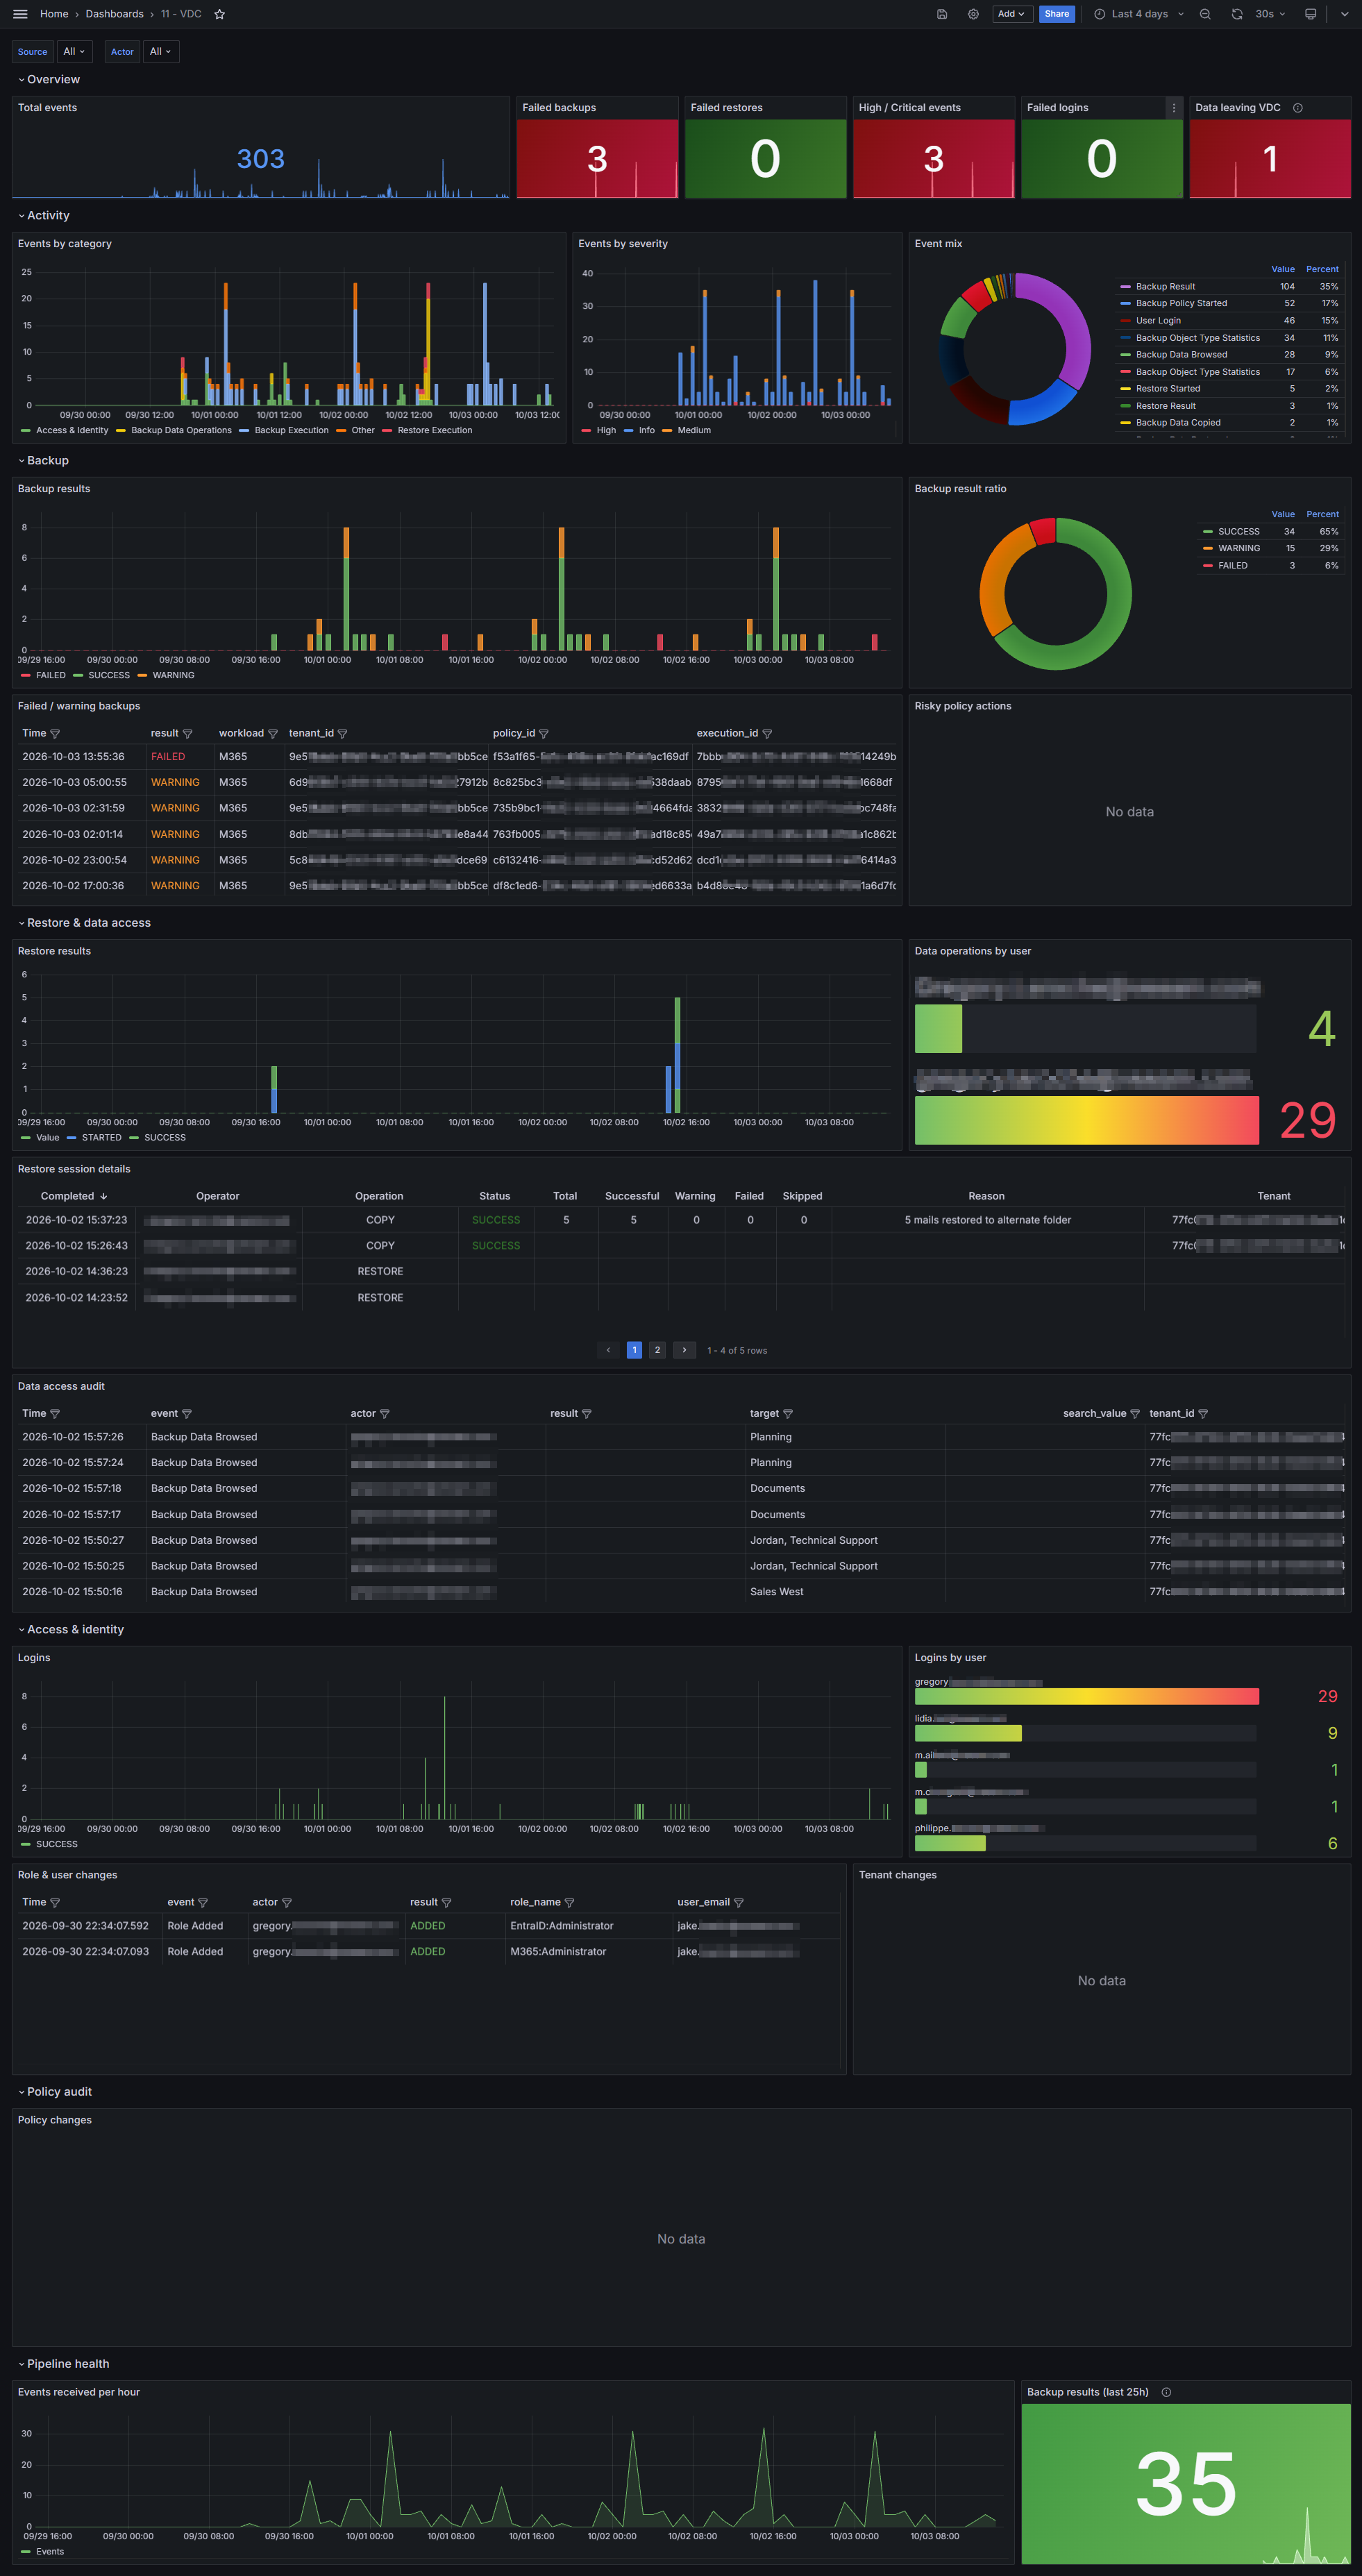
Mine looks like the example below, and of course I won’t leave you alone with a blank dashboard and a pile of InfluxQL queries. 😉
I’ll share the full dashboard configuration with you, so you can use it as a starting point and then tweak, break, improve, and customize it until it fits your own monitoring needs.
This is how it looks currently:
Click below to download this dashboard and import it to your Grafana instance:
And that’s it for this one my dear tech community! 😊
I hope you had as much fun reading it as I had digging into this new VDC SIEM integration, and especially the Generic Webhook capability. There’s a lot you can do with it once the events start flowing!
Now go polish that dashboard, add a few shiny panels, and make it look as good as the data deserves! ✨
See you in the next article.
Written with ❤️ by Greg, for my dear tech community.
